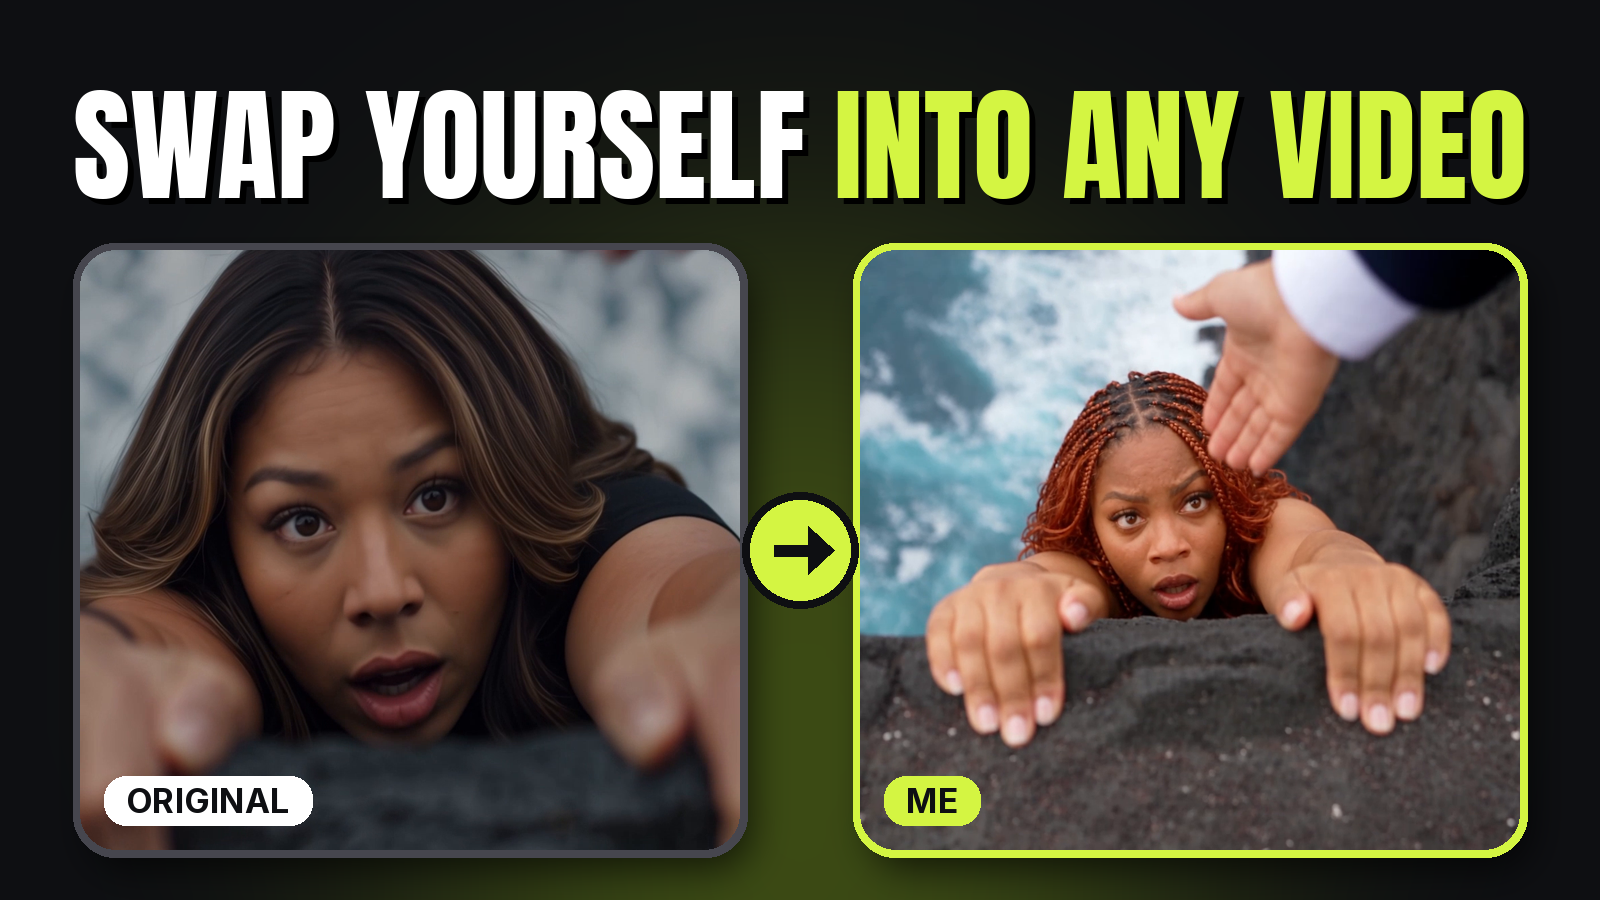
You've seen the viral videos where someone drops themselves into another video: same moves, same camera, but it's them in the scene. Here's how to make one in 3 steps.
You find the clip, ChatGPT writes a detailed prompt for you, and Higgsfield Genjutsu makes the video. Genjutsu is a Higgsfield model that takes the motion from a reference video and puts the people in your photos into it.
By the end, you'll have your own version of the scene, with you as the main character. The prompt below is the exact one I used for the cliff video.